Data preparation and validation tooling for large social-media datasets at NoLimit Indonesia.
Role
Data Science Intern
Period
July — November 2025
Status
Completed
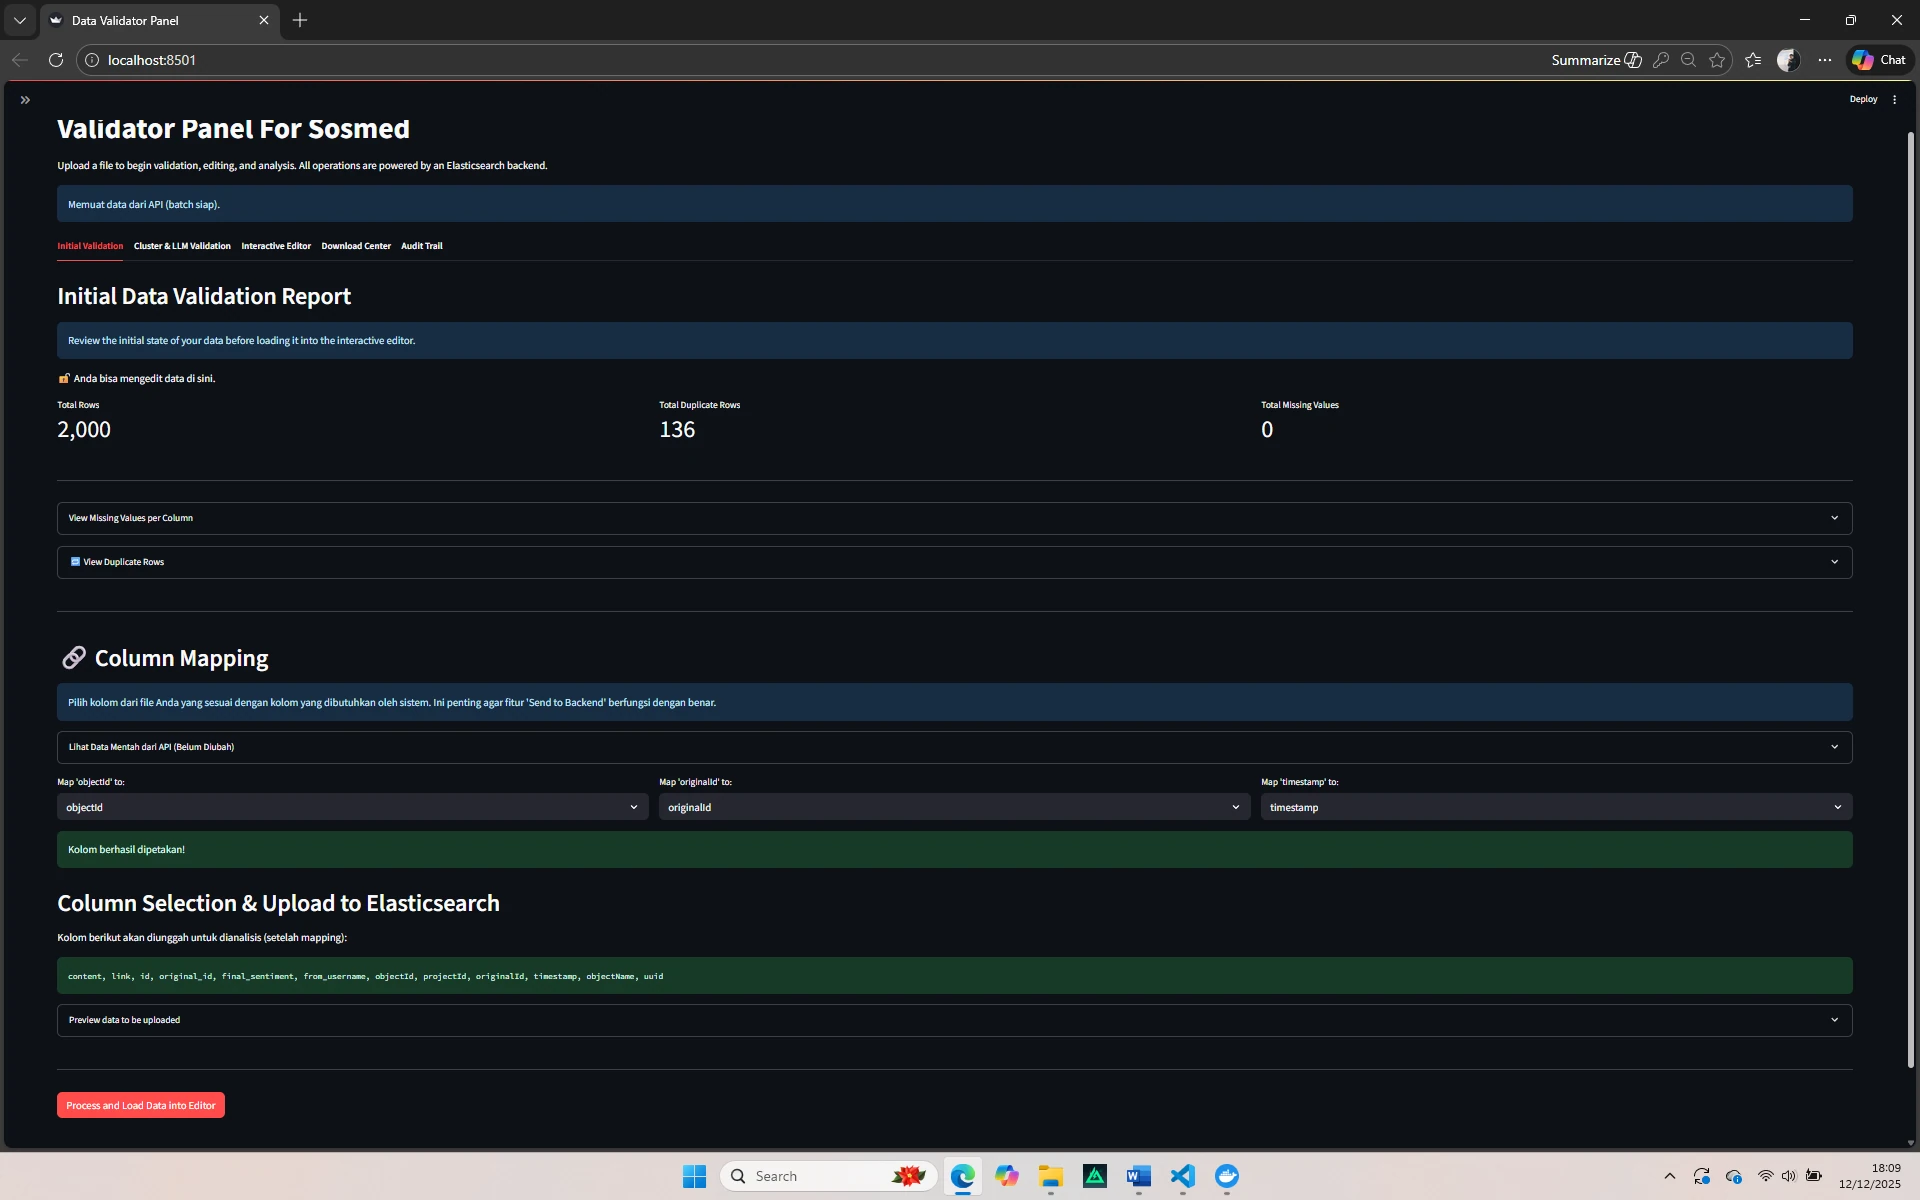
Validator Panel initial data review and column mapping from the owner's internship activity report
The problem
Large social-media datasets need to be retrieved, cleaned, reviewed, and labeled before they can support sentiment-model development.
Contribution & scope
Documented role: Data Science Intern.
Project implementation
A Streamlit Validator Panel supporting uploads up to 600 MB and direct API / Elasticsearch retrieval.
Four review modes: keyword-based batch correction, embedding-based clustering, LLM labeling per row, and grouping by object or entity.
An interactive editor, corrected-data exports, and backend updates, supported by audit trails and three user-access roles.
Data preparation workflows for large social datasets, refined through feedback and user acceptance testing with the validator team.
The approach
I developed a Python and Streamlit panel around the validator team's review process. It brings API and file imports, text preparation, keyword-based correction, embedding-based clustering, and LLM-assisted labeling into one workflow. Reviewers can inspect and edit results before exporting corrected data or updating the backend. Validator Panel and Social Data Validator refer to this same internship tool.
Architecture & workflow
01APIs / Elasticsearch
02Data retrieval
03Cleaning + preparation
04Validation + labeling
05Audit trail
06Model-ready data
Technical challenges
Preparing and reviewing large volumes of social text consistently.
Connecting model-development data to practical validation and audit workflows.
Project views
Initial review and column mapping, from the internship activity report. Counts shown belong to this example batch and are not production-volume or performance results.
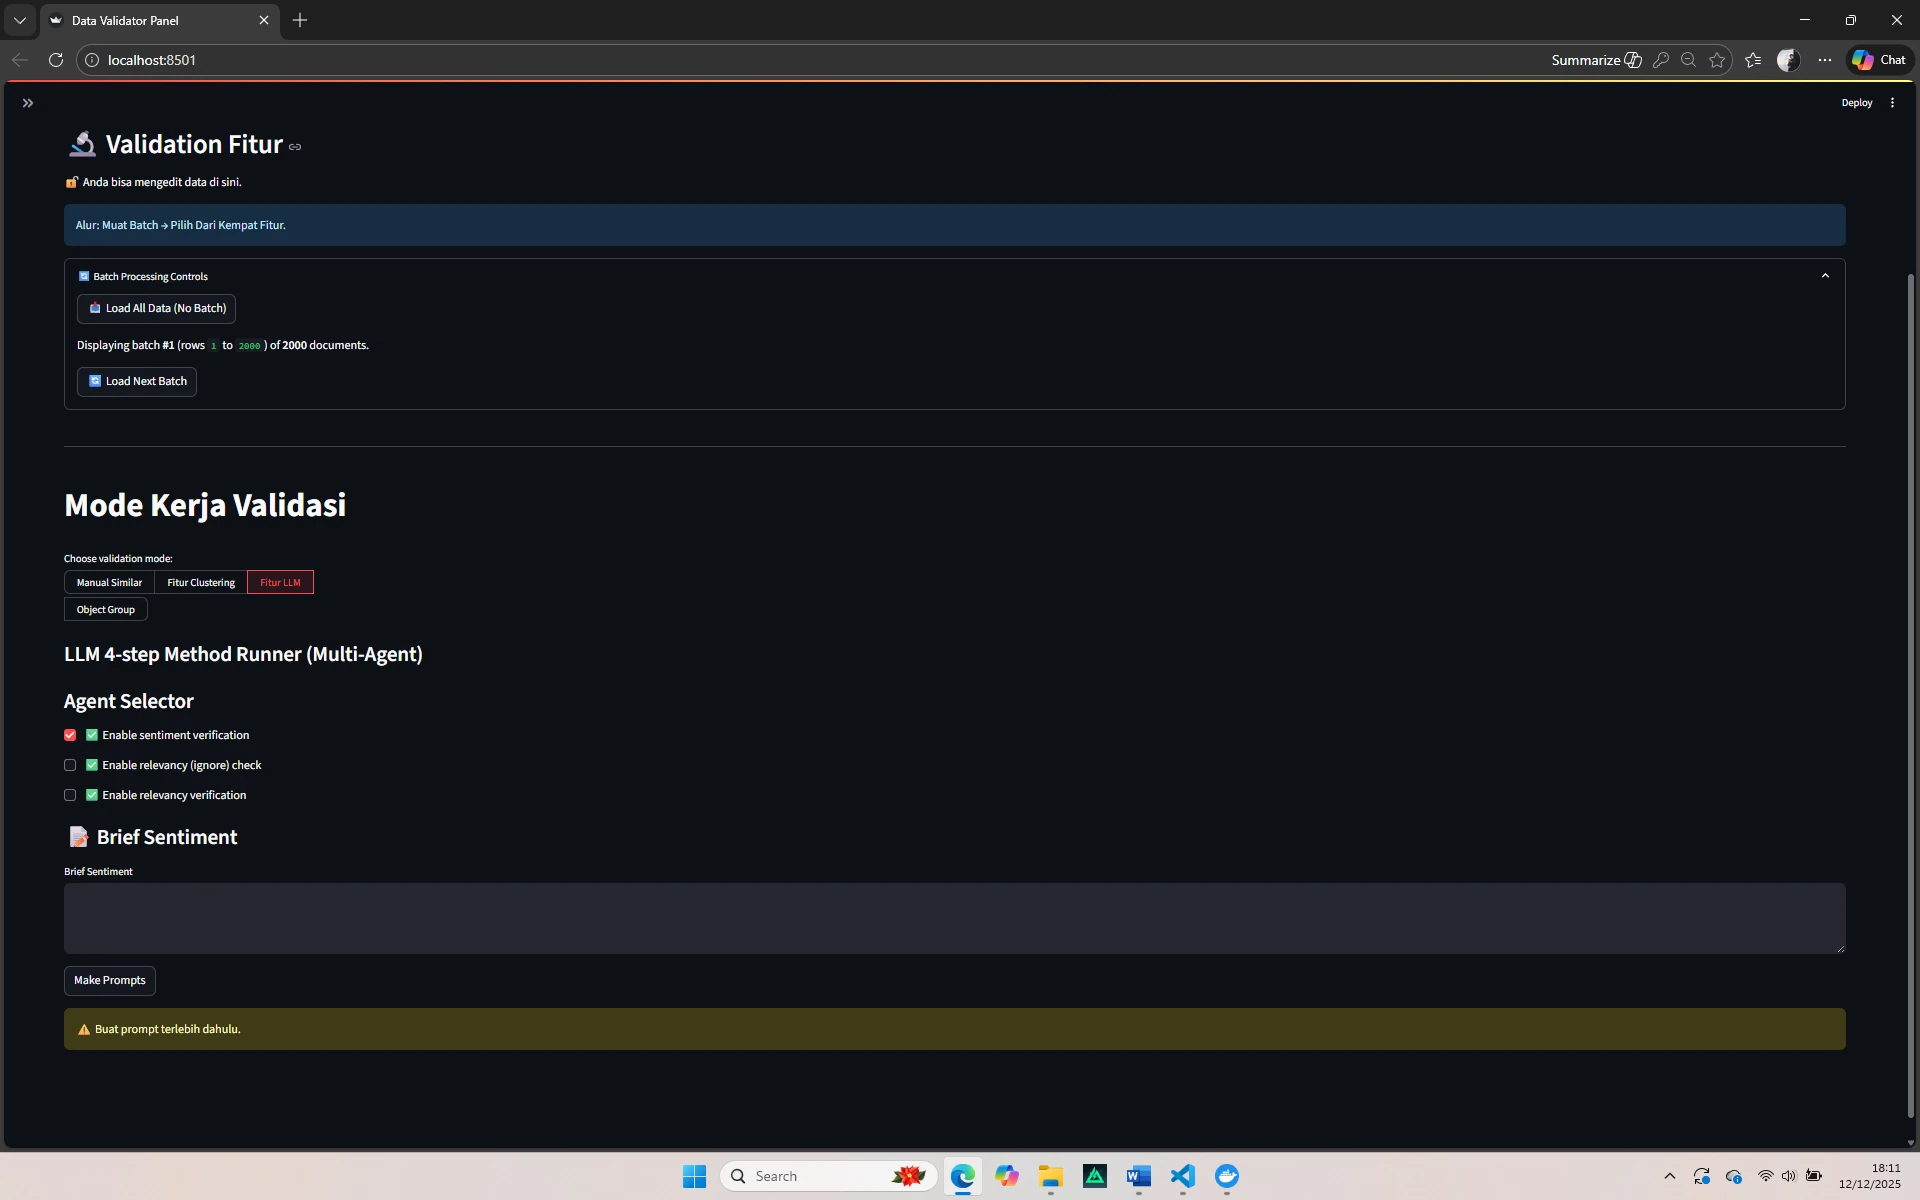
LLM-assisted review controls, from the internship activity report. The screenshot shows configuration and workflow, rather than an evaluated model result.
This case study summarizes an internal internship implementation; source code and validation datasets are not publicly linked for independent review.
Upload and processing figures in the CV describe reported tool scope, not a published performance benchmark.
The activity report and screenshots document implementation scope. They do not establish a measured productivity improvement or a model accuracy benchmark.
What I learned
Model development depends on usable tools for reviewing data and tracing labeling decisions.
Access roles and audit trails are part of a practical data workflow.